Where the milliseconds went
A 32-core node sitting at 2% load, a one-millisecond network, and half the queries taking 40 ms. Three things we found while measuring instead of guessing, including one optimisation that did not work and one that deadlocked.
On this page · 4 sections
The complaint was vague in the way real complaints are: it feels slow, and the server does not look busy. Both halves were true. The node was at 2% load, the round trip on the LAN was under a millisecond, the analyzer answered a hover in one to four milliseconds, and an agent’s query still took 40 ms often enough to notice. Nothing in that list adds up to 40, which is the useful part: when the total is bigger than the sum of the phases you are measuring, you are not measuring the right phases.
So the client learned to print them. Connect, sync, handshake, initialize, query, each phase on its own line, turned on by an environment variable.
# first query after the workspace had been evicted: the load is inside the query
[timing] total=7781.1ms connect=5.4ms preflight_sync=172.5ms handshake=7.3ms
         initialize=0.6ms did_open_sent=5.2ms query_response=7590.2ms

# the same command once the engine is resident
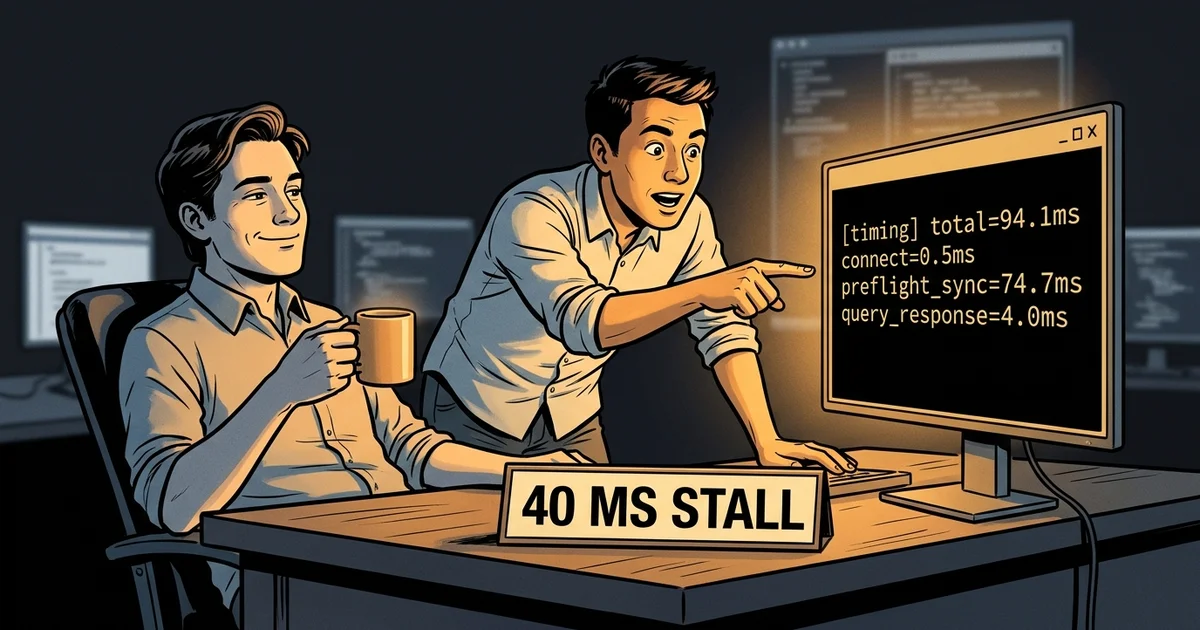
[timing] total=94.1ms connect=0.5ms preflight_sync=74.7ms handshake=7.3ms
         initialize=0.6ms did_open_sent=7.0ms query_response=4.0ms
Two things fall out of those two lines. The analyzer is not the cost, once it is warm: 4 ms
of the 94. And the largest remaining phase is on the laptop, not on the node, because a
one-shot CLI call asks git what changed before it asks anything else.
The distribution that came back was not a slow average. It was bimodal: half the queries were fast, and the other half were fast plus 32 to 43 milliseconds.

A 40 ms number with a name
A stall that lands on the same few tens of milliseconds every time is not contention, it is a timer. This one is two of them, interacting, and they are both older than most of the code they slow down.
Nagle’s algorithm holds a small write until the previous data has been acknowledged, so that a program writing a byte at a time does not put a packet on the wire per byte. Delayed acknowledgement, on the other side, holds the acknowledgement for up to 40 ms hoping to bundle it with a reply. Our query is two writes: a didOpen with the document, then the hover request. The first write goes out, the second is held by Nagle waiting for an ACK, and the ACK is held by the peer waiting for data. They wait for each other until the delayed-ACK timer fires. The measured stall, 32 to 43 ms, is that timer.
The fix is one line per socket, TCP_NODELAY, on the client connect, on the gateway accept, and on the gossip connections between nodes. The server round trip is now p50 around 1 ms, and a release-build client’s full round, connect to answer, is 0.89 ms from a node on the same switch. Everybody knows about Nagle. Nobody checks for it, because the symptom is not an error, it is a number that looks like an unlucky average.
The second finding came free with the first: our own measurements had been lying by an order of magnitude whenever we ran a debug-build client. The wire protocol’s serialisation and the path translation are cheap in release and not cheap at all unoptimised, which inflated the client-side phases by 10 to 100 times and pointed at the wrong layer. Measurements are taken with release builds now, and a phase that only appears in one build profile is a bug in the measurement.
The optimisation that did not work
The 45-second first load of a Rust workspace is our largest remaining number, so we tried to hide it behind the analyzer’s own background priming: as soon as a workspace loads, prime the caches for the local crates, so the first real query finds them warm.
It did not help. rust-analyzer’s parallel_prime_caches warms the symbol indexes and item trees, but not the body inference that a hover on a function actually needs: the first semantic diagnostics of a large crate still took 28.6 s, unchanged. Running full diagnostics per crate does warm it, and takes minutes per workspace, which is worse than the thing it fixes. We closed the issue as not planned and kept the branch for reference. The eviction timer went up instead: a resident engine that is never allowed to go cold is cheaper than any attempt to warm a cold one.
The experiment did leave one permanent rule, which it taught us by hanging twice. In Salsa, applying a change first requests cancellation and then waits until every outstanding analysis snapshot is released, and a snapshot only notices the cancellation while it is running a query. A snapshot that is created and then parked, held in a struct, awaited later, makes the next write block forever: the write waits for the snapshot, and the snapshot waits to be used. Both hangs looked identical in ps: 37 threads in futex_wait with the load average at zero, which is the signature of a lock, never of compilation. Take a snapshot, use it immediately, never hold one across a write or an await.
| what an agent pays today | measured |
|---|---|
| server round trip | p50 ~1 ms |
| full round from a release-build client | 0.89 ms |
| a tool call on a persistent session | ~10 ms |
| a one-shot CLI query | ~80 ms, of which ~70 ms is git |
What we measure now
- Per-phase timing in the client, on demand, in release builds only.
- Every request, command and sync round on a node becomes one event with its duration, which agent asked, from which host, against which workspace;
prod-code metricsaggregates them across the cluster with p50 and p95 per agent, host, workspace and method. - A stall that is a constant is a timer, and a timer has a name. Look it up before optimising anything around it.
What it does not do yet
- The metrics events are appended to a JSONL file per node per day and kept in a 200k-event ring in memory; nothing prunes the files and nothing ships them anywhere.
- Sync rounds are recorded before the handshake, so they carry the workspace and the byte count but not which agent caused them.
- The per-phase timing is a client-side environment variable, not something an agent can turn on for one call.
- The 45 s cold load is still there. We decided to keep engines resident longer rather than make loading faster, which is a scheduling answer to a compute problem and will not survive a much larger fleet.
Measure the phases before optimising the total. Ours said the analyzer was never the problem:
it was a protocol default from 1984 on one side and our own git invocations on the other,
and neither would have been found by making the fast thing faster.
Cite this article
Alexander Panasenko (2026-09-24). Where the milliseconds went. https://prod.codes/blog/where-the-milliseconds-went/