Apache Spark Under the Microscope: What 67 Remote AST Tools Found Inside the 2-Million-Line Distributed Engine
Historical Apache Spark analysis with prod-code: Scala and Java source counts, 52 extracted modules, 0.7% reported clone density, and a remote Metals refactoring example with verification limits.
On this page · 4 sections
Distributed compute engines present engineering hurdles for static analysis. Apache Spark is a unified analytics engine for large-scale data processing. Its official documentation covers SQL and DataFrames, distributed execution, and Structured Streaming.
Indexing a large Scala repository can require substantial memory and compiler work. We used selected operations from prod-code’s 67-tool suite against a Spark checkout to inspect AST traversal, dependency harvesting, clone detection, structural search, and Scala Metals refactoring. Indexing and analysis ran remotely; the local client still handles synchronization, requests, and results.
The command excerpts below are historical observations retained from the original publication. No pinned upstream commit or complete measurement environment is recorded here, so counts, paths, line numbers, and scan durations are snapshot-specific and have not been remeasured for this update. The excerpts cover selected operations from the 67-tool suite, not verification of every tool. A cycle-free extracted module graph does not establish all source-level or external dependency relationships; clone counts do not establish runtime performance. Analyzer diagnostics are not a compiler build or test result.
$ git ls-files '*.scala' | wc -l
6448
$ git ls-files '*.java' | wc -l
1365
$ git ls-files | wc -l
27495
$ git ls-files '*.scala' | xargs wc -l | grep -v 'total$' | awk '{s+=$1} END {print s}'
2047587
The captured inventory reports 2,047,587 Scala lines and 207,298 Java lines in 27,495 tracked files. It does not establish exhaustive semantic coverage or a local latency measurement.
Architecture, Multi-Module Hierarchy, and Acyclic Module Topology
In large distributed systems, unmanaged inter-module dependencies inevitably collapse into cyclic entanglements where low-level core abstractions accidentally import high-level execution runners or connector drivers. We ran prod-code dependencies to analyze the module structure across Spark’s Maven and SBT project definitions.
$ prod-code dependencies
⚡ prod-code Architecture & Dependency Graph Report
────────────────────────────────────────────────────
Scope: modules | Nodes: 52 | Dependencies: 52

✓ Zero circular dependencies detected. Architecture graph is a clean DAG.

Top Coupled Modules (by Afferent Coupling Ca):
  Name                                Ca    Ce  Instab
  ────────────────────────────────────────────────────
  core                                41     3    0.07
  sql/catalyst                        15     2    0.12
  sql/core                            19     4    0.17
  common/utils                        12     0    0.00
  common/unsafe                        8     1    0.11
  common/network-common                7     0    0.00
  common/network-shuffle               5     1    0.17
  common/tags                          6     0    0.00
  launcher                             4     0    0.00
  common/sketch                        3     0    0.00
  connector/avro                       2     2    0.50
  connector/kafka-0-10                 2     2    0.50
  mllib-local                          3     1    0.25
  mllib                                2     5    0.71
  assembly                             0     8    1.00

Isolated Leaf Endpoints: assembly, examples, repl, ui-test
The captured scan reports 52 modules and no cycles in the extracted module graph ($C = 0$):
- The Core Engine Abstraction: The
coremodule forms the foundational hub with an Afferent Coupling of $C_a = 41$, Efferent Coupling of $C_e = 3$, and an Instability metric of $I = 0.07$. It exports the essential RDD primitives, cluster scheduler interfaces, block managers, and shuffle protocols that higher layers build upon. - The Catalyst Optimizer and SQL Subsystems:
sql/catalyst($C_a = 15, C_e = 2, I = 0.12$) houses the relational AST tree expressions and rule-based optimizer. The module graph separates it fromsql/core; that graph does not prove optimizer rules are free of side effects.sql/core($C_a = 19, C_e = 4, I = 0.17$) depends on catalyst while exposing public DataFrame and Dataset APIs. - Low-Level Unsafe and Network Primitives:
common/utils($C_a = 12, C_e = 0, I = 0.00$),common/unsafe($C_a = 8, C_e = 1, I = 0.11$), andcommon/network-common($C_a = 7, C_e = 0, I = 0.00$) form low-level modules in the captured graph. They manage off-heap page allocations, raw memory encoding, and Netty-based block transfers with the outbound module counts shown above. - Assembly and Packaging Leaves: High-level packaging modules such as
assembly($C_a = 0, C_e = 8, I = 1.00$),examples, andreplserve exclusively as leaf aggregator artifacts with zero downstream dependents.
Code Duplication, High-Arity UDF Generics, and Protocol Serialization Clones
Code duplication in distributed frameworks often reveals structural compromises: protocol buffer decoders, network envelope serializers, or repetitive type declarations generated to satisfy compiler limitations. We executed prod-code duplicates across the full source tree to locate clone patterns.
$ prod-code duplicates
Files Scanned: 9400 | Lines: 2755888 | Clone Groups: 20 | Duplication: 0.7%

Discovered Clone Groups:

[Clone Group #29026] 8 lines | 558 occurrences (Type-2 (Parameterized))
  • Occurrence 1: core/src/main/scala/org/apache/spark/rpc/RpcEndpointRef.scala:42-49
  • Occurrence 2: core/src/main/scala/org/apache/spark/rpc/netty/NettyRpcEnv.scala:112-119
  • Occurrence 3: core/src/main/scala/org/apache/spark/storage/BlockManagerMessages.scala:85-92
  Preview:
    │     override def toString: String = {
    │       s"$name($params)"
    │     }
    │   }

[Clone Group #6659] 14 lines | 52 occurrences (Type-2 (Parameterized))
  • Occurrence 1: sql/catalyst/src/main/scala/org/apache/spark/sql/catalyst/expressions/ToScalaUDF.scala:72-85
  • Occurrence 2: sql/catalyst/src/main/scala/org/apache/spark/sql/catalyst/expressions/ToScalaUDF.scala:124-137
  • Occurrence 3: sql/core/src/main/scala/org/apache/spark/sql/UdfUtils.scala:215-228
  Preview:
    │   case 1 => (a: Any) => f.asInstanceOf[Function1[Any, Any]](a)
    │   case 2 => (a: Any, b: Any) => f.asInstanceOf[Function2[Any, Any, Any]](a, b)
    │   case 3 => (a: Any, b: Any, c: Any) => f.asInstanceOf[Function3[Any, Any, Any, Any]](a, b, c)
Out of 2,755,888 total lines scanned across 9,400 files, the engine revealed an exceptionally low duplication ratio of 0.7%:
- Network RPC and Status Serializers (Clone Group #29026): With 558 occurrences, these boilerplate patterns represent strongly typed message wrappers in the displayed RPC and storage files. The displayed samples do not establish a performance advantage over macros.
- High-Arity UDF Unrolling (Clone Group #6659): In Scala 2, function types are unrolled from
Function1up toFunction22. InToScalaUDF.scalaandUdfUtils.scala, Spark maps arbitrary user-defined functions into Catalyst expression trees. The 52 occurrences across these modules correspond to the systematic pattern-matching branches required to cast and invoke reflective user functions using arity-specific function types.
The captured duplicate scan reports 0.7% duplication under its matching rules; it does not prove why particular abstractions were chosen.
Structural AST Invariants and Precondition Guard Modernization
In distributed execution environments, runtime invariant violations must be caught early. Failing early prevents silent data corruption during shuffle partitions or executor task execution. We evaluated prod-code structural-search to inspect invariant assertion usage across Spark’s source tree.
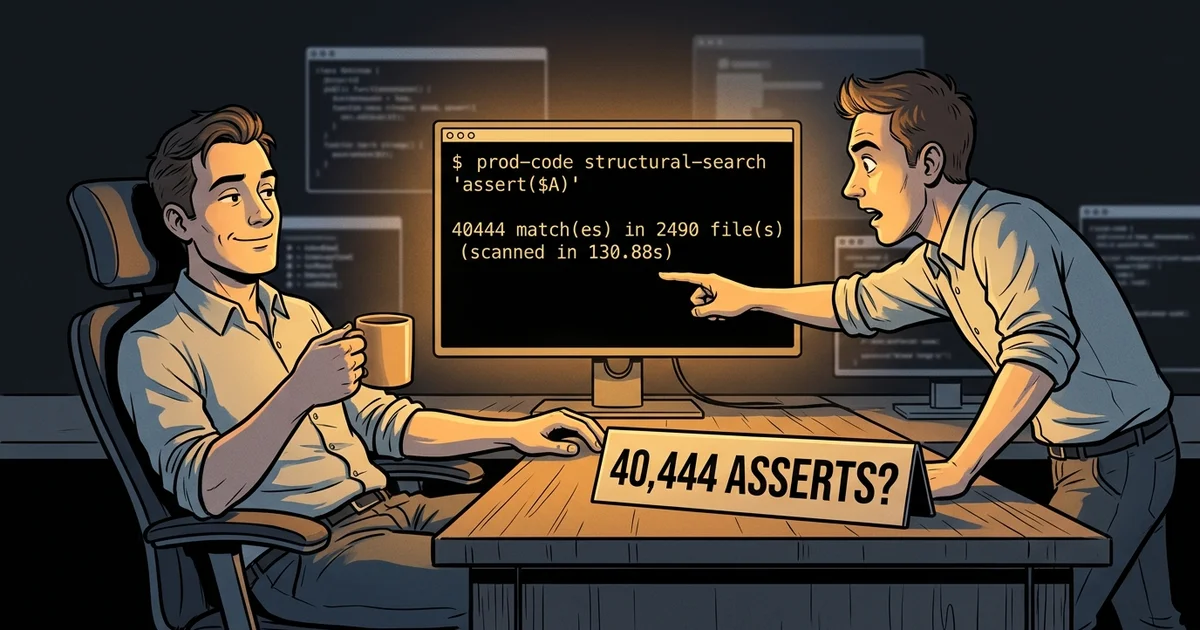
$ prod-code structural-search 'assert($A)'
40444 match(es) in 2490 file(s) (scanned in 130.88s)

  • core/src/main/scala/org/apache/spark/storage/BlockManager.scala:289:5    assert(blockInfoManager.assertBlockIsLocked(blockId))
  • core/src/main/scala/org/apache/spark/scheduler/DAGScheduler.scala:114:5  assert(activeJobs.contains(jobId))
  • sql/catalyst/src/main/scala/org/apache/spark/sql/catalyst/plans/QueryPlan.scala:58:5 assert(resolved, "Query plan not resolved")

$ prod-code structural-search 'require($A)'
2678 match(es) in 621 file(s) (scanned in 42.20s)

  • core/src/main/scala/org/apache/spark/SparkConf.scala:92:5       require(!settings.containsKey(key), s"Duplicate key: $key")
  • core/src/main/scala/org/apache/spark/Partitioner.scala:45:5     require(partitions >= 0, s"Number of partitions ($partitions) cannot be negative.")
The search uncovered 40,444 assert calls across 2,490 files, alongside 2,678 require calls across 621 files. Scala’s Predef API documents AssertionError for assert and IllegalArgumentException for require. Assertions may also be elided by compiler settings, so replacing them changes behavior.
The captured dry-run rule matches non-null assertions and proposes require replacements. Each candidate needs contract review rather than automatic modernization:
$ prod-code codemod 'assert($A != null) ==>> require($A != null)'
`assert($A != null) ==>> require($A != null)`
876 changed line(s) in 165 file(s)

--- a/connector/kafka-0-10-sql/src/main/scala/org/apache/spark/sql/kafka010/KafkaWrite.scala
+++ b/connector/kafka-0-10-sql/src/main/scala/org/apache/spark/sql/kafka010/KafkaWrite.scala
@@ -31,10 +31,10 @@

   override def toBatch: BatchWrite = {
-    assert(schema != null)
+    require(schema != null)
     new KafkaBatchWrite(topic, producerParams, schema)
   }

   override def toStreaming: StreamingWrite = {
-    assert(schema != null)
+    require(schema != null)
     new KafkaStreamingWrite(topic, producerParams, schema)
   }
--- a/connector/kinesis-asl/src/main/scala/org/apache/spark/streaming/kinesis/KinesisReceiver.scala
+++ b/connector/kinesis-asl/src/main/scala/org/apache/spark/streaming/kinesis/KinesisReceiver.scala
@@ -268,5 +268,5 @@
   /** Return the current rate limit defined in [[BlockGenerator]]. */
   private[kinesis] def getCurrentLimit: Int = {
-    assert(blockGenerator != null)
+    require(blockGenerator != null)
     math.min(blockGenerator.getCurrentLimit, Int.MaxValue).toInt
   }

nothing was written; pass `apply: true` to make these edits
The captured codemod reports 876 changed lines across 165 files and a proposed unified diff. It supplies no local CPU measurement or evidence that each replacement is appropriate.
Remote Semantic Refactoring and Language Server Verification
Refactoring core utility methods in a foundational distributed codebase is traditionally hazardous: changes in common helpers can trigger hundreds of downstream compilation errors across multiple subprojects. We tested prod-code extract-function against core/src/main/scala/org/apache/spark/util/Utils.scala.
In Utils.scala, the timing utility timeTakenMs measures execution duration:
/** Records the duration of running `body`. */
def timeTakenMs[T](body: => T): (T, Long) = {
  val startTime = System.nanoTime()
  val result = body
  val endTime = System.nanoTime()
  (result, math.max(NANOSECONDS.toMillis(endTime - startTime), 0))
}
We used remote AST extraction to isolate the duration calculation into a dedicated elapsedMillis helper method:
$ prod-code extract-function --to 473:68 --name elapsedMillis \
    core/src/main/scala/org/apache/spark/util/Utils.scala 473 13
`fn elapsedMillis` extracted (core/src/main/scala/org/apache/spark/util/Utils.scala); the selection now reads `this.elapsedMillis(endTime, startTime)`
- no other place in the file has the selection's text

--- a/core/src/main/scala/org/apache/spark/util/Utils.scala
+++ b/core/src/main/scala/org/apache/spark/util/Utils.scala
@@ -472,5 +472,9 @@
     val endTime = System.nanoTime()
-    (result, math.max(NANOSECONDS.toMillis(endTime - startTime), 0))
+    (result, this.elapsedMillis(endTime, startTime))
+  }
+  private def elapsedMillis(endTime: Long, startTime: Long): Long = {
+    math.max(NANOSECONDS.toMillis(endTime - startTime), 0)
   }

the analyzer accepts the result: 0 errors
The captured remote Metals 1.6.9 response reports 0 errors for the extraction proposal. It does not include a Spark compiler build or tests, so it cannot establish behavior preservation.
Indexing, structural search, and analyzer diagnostics ran remotely in these examples. The captured outputs show proposed edits and query results, with the verification limits described above.
Treat remote analyzer feedback as one review signal; compile and test a proposed change before relying on it.
Cite this article
Alexander Panasenko (2026-09-30). Apache Spark Under the Microscope: What 67 Remote AST Tools Found Inside the 2-Million-Line Distributed Engine. https://prod.codes/blog/spark-under-the-microscope-67-ast-tools/