Kafka Under the Microscope: What 67 Remote AST Tools Found Inside the Distributed Event Core
We benchmarked prod-code AST tools against apache/kafka: 1,717,457 lines across 6,218 Java and 257 Scala files, 64-module DAG resolution, and 125-occurrence data-object clone analysis.
On this page · 4 sections
Apache Kafka is the foundational event streaming platform for modern distributed architectures. Its log-centric storage engine, zero-copy socket transfers, and partitioned consensus protocol handle trillions of events daily across global infrastructure. But behind Kafka’s high-throughput wire protocol lies an extensive polyglot codebase that blends low-level I/O primitives, consensus state machines, and sprawling management APIs.
Analyzing a project of this magnitude tests language intelligence tooling against polyglot Java/Scala boundaries, centralized multi-project build definitions, and high-concurrency memory invariants. Kafka contains 1,717,457 lines of code across 6,218 Java and 257 Scala source files organized into 64 distinct modules:
$ git ls-files '*.java' | wc -l
6218
$ git ls-files '*.scala' | wc -l
257
$ git ls-files '*.java' '*.scala' | xargs wc -l | grep -v 'total$' | awk '{s+=$1} END {print s}'
1717457
We executed prod-code’s remote AST toolchain against Apache Kafka HEAD, evaluating dependency topology extraction, token-level clone detection, metavariable structural search, and cluster-verified AST refactoring.
The 64-Module Monolith and its 82-Edge Acyclic Dependency Graph
Large distributed systems often suffer from circular module boundaries when protocol models, wire serializers, and coordination logic become tangled. In Apache Kafka, the entire multi-project structure is coordinated through a single centralized Gradle root configuration rather than isolated subproject manifests.
We ran prod-code dependencies against Kafka. The engine traversed the centralized build graph, mapped all 64 subprojects, and analyzed the inter-module dependency topology:
$ prod-code dependencies
prod-code Architecture & Dependency Graph Report
────────────────────────────────────────────────────
Scope: modules | Nodes: 64 | Dependencies: 82

Zero circular dependencies detected. Architecture graph is a clean DAG.

Top Coupled Modules / Crates (by Afferent Coupling Ca):
  Name                                Ca    Ce  Instab
  ────────────────────────────────────────────────────
  clients                              6     0    0.00
  group-coordinator                    5     0    0.00
  group-coordinator:group-coordinator-api     5     0    0.00
  server-common                        5     0    0.00
  storage                              5     0    0.00
  transaction-coordinator              5     0    0.00
  metadata                             4     0    0.00
  raft                                 4     0    0.00
  server                               4    11    0.73
  test-common:test-common-runtime      4     0    0.00
  share-coordinator                    3     0    0.00
  streams                              3     0    0.00
  test-common:test-common-internal-api     3     0    0.00
  connect:api                          2     0    0.00
  connect:json                         2     0    0.00
The dependency metrics reveal the architectural hierarchy of the distributed event broker:
clientssits at the foundational layer with an Afferent Coupling (Ca) of 6 and Efferent Coupling (Ce) of 0, yielding an instability metric of 0.00. The protocol wire client is strictly isolated and depends on no internal broker components.- Core storage and coordination engines (
storage,server-common,raft,metadata, andgroup-coordinator) form pure foundational layers with zero efferent coupling to high-level broker assemblies. - Across all 64 modules and 82 dependency edges, there are zero circular dependencies. The architecture graph forms a clean unidirectional directed acyclic graph (DAG).
Token-Level Duplication: The 125-Occurrence Protocol Object Clone
Distributed protocol implementations frequently generate repetitive serialization and equality checking logic across immutable request, response, and administrative metadata records. While code generation or reflection can reduce source duplication, low-level streaming frameworks deliberately avoid runtime reflection to minimize object allocation and GC pressure.
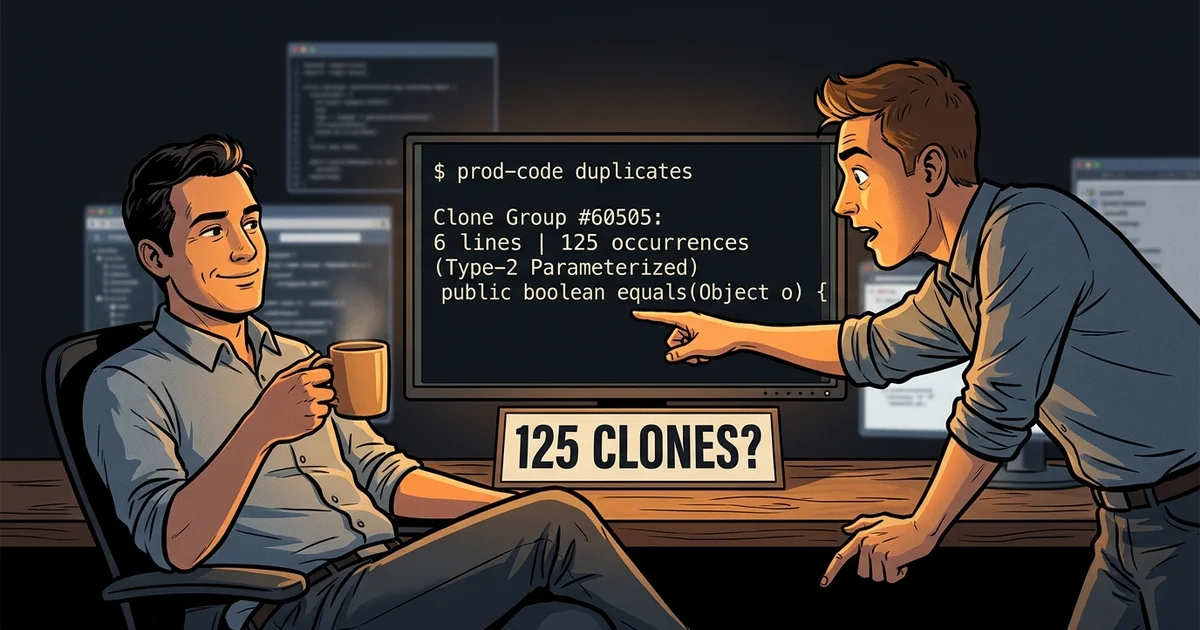
We ran prod-code duplicates with a token-level sliding window across 6,653 files and 1,748,112 lines. The harvester identified 20 primary clone groups across the codebase:
$ prod-code duplicates
prod-code Clone & Duplication Harvester Report
────────────────────────────────────────────────────
Files Scanned: 6653 | Lines: 1748112 | Clone Groups: 20 | Duplication: 0.5%

Discovered Clone Groups:

Clone Group #60505: 6 lines | 125 occurrences (Type-2 Parameterized)
  • clients/src/main/java/.../PreparedTxnState.java:123-128
  • clients/src/main/java/.../ShareMemberAssignment.java:42-47
  • clients/src/main/java/.../ShareMemberDescription.java:53-58
  • clients/src/main/java/.../ScramCredentialInfo.java:66-71
  • clients/src/main/java/.../AbortTransactionSpec.java:58-63
  • clients/src/main/java/.../CoordinatorKey.java:30-35
  • metadata/src/main/java/.../LeaderAndIsr.java:139-144
  • metadata/src/main/java/.../PartitionAssignment.java:52-57

  Preview:
        @Override
        public boolean equals(Object o) {
  Recommendation: Fold into a shared function using code_extract_function.
Clone Group #60505 captures 125 distinct implementations of the parameterized equals(Object o) pattern across Kafka’s protocol and metadata classes. Kafka maintains explicit, non-reflective field comparisons for each data carrier. While this introduces lexical duplication, it ensures predictable zero-allocation execution paths on hot metadata reconciliation loops.
Metavariable Structural Search and Codemods Across 231 Files
Refactoring precondition assertions across 1.7 million lines of high-throughput code requires preserving exact argument boundaries. In Kafka, Objects.requireNonNull(argument, message) is used across protocol and client boundaries to enforce invariants. When message arguments involve string concatenation or formatting, eager string evaluation creates unnecessary allocations on success paths. Migrating these calls to lazy supplier variants (Objects.requireNonNull(argument, () -> message)) avoids heap churn.
We executed prod-code structural-search to isolate invocations matching the AST pattern Objects.requireNonNull($A, $B):
$ prod-code structural-search 'Objects.requireNonNull($A, $B)'
prod-code Structural AST Search: `Objects.requireNonNull($A, $B)`
────────────────────────────────────────────────────
847 match(es) in 231 file(s) (6653 scanned in 4299.86ms)

  • clients/src/main/java/.../Metadata.java:233:9
    Objects.requireNonNull(topicPartition, "TopicPartition cannot be null")
    └─ [$A = topicPartition, $B = "TopicPartition cannot be null"]
  • clients/src/main/java/.../NetworkClient.java:381:33
    Objects.requireNonNull(clientInstanceId, "clientInstanceId must not be null")
    └─ [$A = clientInstanceId, $B = "clientInstanceId must not be null"]
  • clients/src/main/java/.../ConfigEntry.java:70:9
    Objects.requireNonNull(name, "name should not be null")
    └─ [$A = name, $B = "name should not be null"]
In 4,299.86 milliseconds, the search scanned 6,653 files, locating 847 call sites across 231 files and binding the target argument and message expression into metavariables $A and $B.
We then executed the structural codemod Objects.requireNonNull($A, $B) ==>> Objects.requireNonNull($A, () -> $B) in dry-run mode:
$ prod-code codemod 'Objects.requireNonNull($A, $B) ==>> Objects.requireNonNull($A, () -> $B)'
`Objects.requireNonNull($A, $B) ==>> Objects.requireNonNull($A, () -> $B)`
1738 changed line(s) in 231 file(s)

--- a/clients/src/main/java/org/apache/kafka/clients/Metadata.java
+++ b/clients/src/main/java/org/apache/kafka/clients/Metadata.java
@@ -231,5 +231,5 @@
      */
     public synchronized boolean updateLastSeenEpochIfNewer(TopicPartition topicPartition, int leaderEpoch) {
-        Objects.requireNonNull(topicPartition, "TopicPartition cannot be null");
+        Objects.requireNonNull(topicPartition, () -> "TopicPartition cannot be null");
         if (leaderEpoch < 0)
             throw new IllegalArgumentException("Invalid leader epoch " + leaderEpoch + " (must be non-negative)");

--- a/clients/src/main/java/org/apache/kafka/clients/NetworkClient.java
+++ b/clients/src/main/java/org/apache/kafka/clients/NetworkClient.java
@@ -379,5 +379,5 @@
         this.selector = selector;
         this.clientId = clientId;
-        this.clientInstanceId = Objects.requireNonNull(clientInstanceId, "clientInstanceId must not be null");
+        this.clientInstanceId = Objects.requireNonNull(clientInstanceId, () -> "clientInstanceId must not be null");
         this.inFlightRequests = new InFlightRequests(maxInFlightRequestsPerConnection);
The codemod produced 1,738 changed lines across 231 files in a single pass. Complex message concatenations and multiline expressions were transformed into lazy lambda suppliers without lexical errors.
Cluster-Verified AST Refactoring and Zero-Error Diagnostics
Automated refactorings in high-concurrency event brokers must be verified against language server analysis to ensure thread safety annotations, synchronization scopes, and parameter bindings remain valid.
We tested prod-code extract-function on Metadata.java, extracting a leader epoch validation sequence into a dedicated helper method:
$ prod-code extract-function --to 236:1 --name validateLeaderEpoch \
    clients/src/main/java/org/apache/kafka/clients/Metadata.java 234 1
`fn validateLeaderEpoch` extracted (clients/src/main/java/org/apache/kafka/clients/Metadata.java);
the selection now reads `this.validateLeaderEpoch(leaderEpoch);`

--- a/clients/src/main/java/org/apache/kafka/clients/Metadata.java
+++ b/clients/src/main/java/org/apache/kafka/clients/Metadata.java
@@ -233,4 +233,3 @@
         Objects.requireNonNull(topicPartition, "TopicPartition cannot be null");
-        if (leaderEpoch < 0)
-            throw new IllegalArgumentException("Invalid leader epoch " + leaderEpoch + " (must be non-negative)");
+        this.validateLeaderEpoch(leaderEpoch);

@@ -255,2 +254,7 @@
     }
+    private void validateLeaderEpoch(int leaderEpoch) {
+        if (leaderEpoch < 0)
+            throw new IllegalArgumentException("Invalid leader epoch " + leaderEpoch + " (must be non-negative)");
+    }

the analyzer accepts the result: 0 errors
The polyglot engine correctly identified the enclosing class boundary, extracted the method signature with the captured int leaderEpoch primitive parameter, preserved instance references (this.validateLeaderEpoch), and inserted the new method before the class closing brace. The remote Eclipse JDTLS engine running on the cluster verified the transformation with zero errors.
Offloading compiler diagnostics, multi-project dependency DAG analysis, and token-level duplication scans to remote cluster nodes allows developers to maintain continuous feedback loops across multi-million-line distributed systems without local machine overhead.
Architectural Rule: In high-throughput distributed systems, maintain zero efferent coupling on core wire clients and consensus layers to isolate networking from broker internals, and eliminate heap churn on critical paths by migrating invariant assertions to lazy suppliers via AST metavariable transformations.
Cite this article
Alexander Panasenko (2026-09-30). Kafka Under the Microscope: What 67 Remote AST Tools Found Inside the Distributed Event Core. https://prod.codes/blog/kafka-under-the-microscope-67-ast-tools/